What Is a UUID? How UUID Versions (v1, v4, v7) Work and Collision Math
Understand UUID architecture, the 8-4-4-4-12 canonical format, and how UUID versions 1, 4, and 7 differ. Learn collision mathematics and database indexing trade-offs.

A Universally Unique Identifier (UUID) is a 128-bit numerical label designed to provide an practically guaranteed unique identity across distributed computer systems without relying on a central registration authority or coordination coordinator. Represented canonically as a 36-character hexadecimal string formatted in an 8-4-4-4-12 pattern—such as f47ac10b-58cc-4372-a567-0e02b2c3d479—UUIDs form the backbone of modern cloud computing, distributed databases, REST APIs, and microservice architectures.
Whenever you create a new record in a database, dispatch an asynchronous task, generate a session token, or synchronize offline mobile data with a central server, you interact with UUIDs. However, not all UUIDs function identically. Older standards like UUID version 1 rely on physical hardware MAC addresses and timestamps, introducing severe privacy and security vulnerabilities. Modern applications rely overwhelmingly on UUID version 4 for pure cryptographic randomness, while the latest IETF specification—RFC 9562, published in May 2024—introduced UUID version 7 to solve catastrophic B-tree database index fragmentation.
This technical guide explains how UUIDs are structured at the bit level, how UUID versions (v1 through v8) work, why the Birthday Paradox governs collision probability, how UUIDs compare to auto-incrementing integer keys, and how to generate cryptographically secure identifiers in your browser using the CoditTools UUID Generator.
What Is a UUID and Why Do Modern Systems Use It?
In centralized database architectures, generating a unique primary key is straightforward. A single relational database engine (such as PostgreSQL or MySQL) maintains an auto-incrementing integer sequence (e.g., 1, 2, 3...). Every time a client inserts a row, the database locks or increments the counter, assigns the integer, and returns the result.
However, this centralized model collapses when software scales into distributed, cloud-native environments. If an application operates across multiple geographical regions, runs dozens of microservices, or permits client applications to record transactions while offline (such as a mobile point-of-sale terminal), every write cannot wait for a single central database sequence. Attempting to coordinate sequential numbers across multiple write nodes causes high latency, network bottlenecks, and split-brain synchronization collisions.
A UUID solves this decentralization problem completely. Because a UUID contains 128 bits of information, the total number of possible combinations is 2128, or roughly 3.4028 × 1038 distinct values. By adhering to standardized generation algorithms defined originally in RFC 4122 and updated in RFC 9562, any computer anywhere in the world can generate an identifier independently with zero network coordination, confident that no other machine has ever generated—or will ever generate—the identical value.

The Anatomy of a UUID: Hexadecimal Format and Bit Allocation
While software developers frequently treat a UUID as a simple string of letters and numbers, a UUID is fundamentally a 128-bit unsigned integer (16 raw bytes). Storing, transmitting, and reading 128 raw binary bits directly would be cumbersome and prone to encoding errors, which is why the IETF standardized the canonical hexadecimal string representation.
The 8-4-4-4-12 Canonical Representation
A standard UUID is written as 32 hexadecimal characters (digits 0–9 and lowercase letters a–f) punctuated by four hyphens into five distinct groups:
This layout yields a fixed length of exactly 36 characters (32 hex digits + 4 hyphens). The five hyphen-separated fields correspond directly to legacy fields established in the original 1980s Apollo Network Computing System (NCS) and OSF Distributed Computing Environment (DCE) standards:
| Field Name | Hex Length | Bit Width | Byte Range | Original RFC 4122 Purpose |
|---|---|---|---|---|
| time_low | 8 chars | 32 bits | Bytes 0–3 | Low 32 bits of the 60-bit timestamp |
| time_mid | 4 chars | 16 bits | Bytes 4–5 | Middle 16 bits of the 60-bit timestamp |
| time_hi_and_version | 4 chars | 16 bits | Bytes 6–7 | Top 4 bits encode UUID version; lower 12 bits hold high timestamp |
| clock_seq_hi_res_clock_seq_low | 4 chars | 16 bits | Bytes 8–9 | Top 2–3 bits encode variant; lower 13–14 bits prevent clock rollback dupes |
| node | 12 chars | 48 bits | Bytes 10–15 | 48-bit IEEE 802 MAC address (or random bits in v4) |
If you are working with binary representations or low-level byte buffers, you can review our companion guide on converting hex, binary, and decimal by hand to understand how place values translate directly between nibbles and raw computer memory.
How to Read Version and Variant Bits
Every valid RFC-compliant UUID contains two embedded structural indicators: the Version nibble and the Variant bits. You can determine the exact type and specification of any UUID simply by inspecting two specific character positions:
- The Version Nibble (Position 15 in canonical string / 13th hex digit): This is the first character of the third group (e.g., in
f47ac10b-58cc-4372-a567-0e02b2c3d479, the version character is4). In binary, this 4-bit nibble occupies bits 48 to 51. A value of0001indicates Version 1,0100indicates Version 4, and0111indicates Version 7. - The Variant Bits (Position 20 in canonical string / 17th hex digit): This is the first character of the fourth group (e.g., in
...-a567-..., the character isa). The top 2 to 3 bits of this byte (bits 64 and 65) define the layout variant. For standard RFC 4122 and RFC 9562 UUIDs, the leading binary bits must be10. Because the remaining two bits in that nibble can be anything (1000to1011in binary), the hex digit will always be one of four values:8,9,a, orb.
If an identifier has any character other than 8, 9, a, or b at character position 20, it does not conform to the modern standard IETF variant (for example, characters starting with c, d, or e indicate legacy Microsoft COM GUID variants or Apollo reserved formats).
UUID vs. GUID: Are They the Same Identifier?
Software documentation frequently uses the terms UUID (Universally Unique Identifier) and GUID (Globally Unique Identifier) interchangeably. In modern web and enterprise development, they refer to the identical 128-bit mathematical concept, but their origins and historical byte ordering differ:
- UUID: The formal standard defined by the Open Software Foundation (OSF) and formalized by the Internet Engineering Task Force (IETF) in RFC 4122 and RFC 9562, as well as the International Telecommunication Union (ITU-T Rec. X.667). UUIDs always mandate big-endian (network byte order) encoding across all fields.
- GUID: Microsoft's implementation of the UUID standard, introduced for the Component Object Model (COM), ActiveX, and Windows Registry. Microsoft GUIDs are traditionally enclosed in curly braces, such as
{F47AC10B-58CC-4372-A567-0E02B2C3D479}, and are frequently written in uppercase. - The Endianness Trap: Historically, Microsoft GUID structures on x86 architectures stored the first three fields (
Data1,Data2, andData3) in little-endian byte order in memory, while storing the remaining two byte arrays in big-endian order. If you directly convert a raw C++ GUID struct to a string on Windows without byte-swapping, you can inadvertently scramble the first 8 bytes. Modern .NET runtimes and modern database drivers normalize this automatically.
When using our online UUID generator, you can toggle between standard canonical lowercase formatting, uppercase formatting, compact format (removing hyphens), and curly brace notation with a single click.

The Complete Breakdown of UUID Versions (RFC 4122 to RFC 9562)
The IETF specification defines eight official versions of UUIDs. Each version uses a distinct method to generate its 128 bits. Understanding these differences is essential for choosing the right version for security, performance, and compliance.
UUID Version 1: Timestamp and MAC Address
UUID v1 combines space and time. It constructs a 60-bit timestamp counting the number of 100-nanosecond intervals since the introduction of the Gregorian calendar (midnight on October 15, 1582). To guarantee uniqueness across machines, it reads the physical 48-bit MAC address of the network interface card into the node field, along with a 14-bit clock sequence to prevent duplicates if the system clock rolls backward.
Why v1 is problematic today:
- Privacy Leak: Anyone inspecting a v1 UUID can decode the exact millisecond the ID was created and extract the hardware MAC address of the server or client machine, exposing physical network topology.
- B-Tree Fragmentation: The timestamp is split into three chunks, and the least significant bits (
time_low) are placed at the beginning of the string. Consecutive UUIDs generated milliseconds apart have completely different starting characters, scattering writes across database index pages.
UUID Version 2: DCE Security
UUID v2 is an obscure variant specified by the Open Group DCE standard. It replaces the low 32 bits of the timestamp with the local user's POSIX UID or GID. Version 2 is rarely implemented in modern web stacks or programming language standard libraries.
UUID Versions 3 and 5: Name-Based Deterministic Hashing
Versions 3 and 5 are deterministic identifiers generated by hashing a namespace identifier (itself a UUID) combined with an arbitrary input string (such as a domain name, URL, or username). If you provide the identical namespace and name, you will always get the identical UUID.
- UUID v3: Uses the MD5 cryptographic hash function. Because MD5 is cryptographically broken and vulnerable to hash collision attacks, RFC 9562 explicitly deprecates v3 for new designs.
- UUID v5: Uses the SHA-1 cryptographic hash function. While SHA-1 is also cryptographically weakened for digital signatures, RFC 9562 permits v5 for deterministic naming because generating second-preimage collisions for 128 truncated bits remains computationally infeasible.
UUID Version 4: Cryptographically Strong Randomness
UUID v4 is by far the most widely adopted UUID version in digital software. Rather than relying on clocks or hardware, v4 populates the entire 128-bit structure with pseudo-random or cryptographically secure random bits, reserving only 4 bits for the version number (0100) and 2 bits for the variant (10).
This leaves exactly 122 bits of pure entropy. Version 4 leaks zero hardware details, exposes zero chronological metadata, and requires no central coordination. When generated with modern cryptographic APIs like Web Cryptography crypto.randomUUID() or Linux /dev/urandom, v4 identifiers are completely unpredictable and safe for public-facing identifiers.
UUID Version 6: Reordered Timestamp (RFC 9562)
Standardized in RFC 9562 to fix the B-tree sorting defect of UUID v1, UUID v6 takes the identical 60-bit Gregorian timestamp from v1 but rearranges the bits so the most significant timestamp bits appear first. This makes v6 lexicographically sortable while maintaining legacy compatibility with v1 data models. However, it still carries the legacy 1582 Gregorian epoch and MAC address baggage.
UUID Version 7: Unix Epoch Milliseconds + Random (RFC 9562)
UUID v7 is the premier modern standard introduced in RFC 9562 (May 2024). It combines the best attributes of timestamp ordering and cryptographic randomness:
- 48-bit Unix Epoch Timestamp: The first 48 bits encode the current Unix timestamp in milliseconds. This timestamp will not overflow until the year 10,889 AD.
- Version & Variant Flags: 4 bits for version (
0111) and 2 bits for variant (10). - 74 Bits of Random Entropy: The remaining bits (12 bits in
rand_aand 62 bits inrand_b) are filled with CSPRNG randomness, providing robust collision resistance even for millions of records created in the same millisecond. - K-Sortable Nature: Because the timestamp is at the beginning, UUID v7 values sort chronologically and lexicographically. Consecutive database inserts append sequentially to B-tree leaves rather than fragmenting pages.
UUID Version 8: Custom Vendor Formats
RFC 9562 defines UUID v8 as an open standard for vendor-specific or experimental implementations that require custom bit layouts (such as combining tenant IDs or specialized distributed counter data) while maintaining valid UUID container conformance.
UUID v4 vs. UUID v7: The Modern Database Primary Key Dilemma
One of the most consequential architectural decisions software engineers face is selecting the identifier format for primary keys in relational database management systems like PostgreSQL, MySQL (InnoDB), SQLite, and Microsoft SQL Server.
The B-Tree Index Fragmentation Problem
Most relational database engines store primary keys inside a B-Tree (or B+ Tree) clustered index. In a clustered index, table rows are physically stored on disk in the exact sorted order of their primary key. When you insert a new record, the database traverses the B-tree to find the appropriate 8KB or 16KB disk page and writes the row.
When you use purely random UUID v4 as a clustered primary key, consecutive inserts scatter uniformly across the entire keyspace:
- Page Splits: Because values arrive in random order, a new record must often be shoehorned into a disk page that is already completely full. The database engine must perform an expensive "page split"—allocating a new disk page, copying half the rows over, and rewriting B-tree node pointers.
- Cache Eviction & I/O Thrashing: In small databases, the entire index fits in memory (RAM buffer pool). But once your table exceeds RAM, every random insert requires reading a random page from disk into cache. Write throughput plummets, and disk I/O spikes exponentially.
- Index Bloat: Repeated page splits leave disk pages only 50% to 70% full on average, wasting gigabytes of disk and memory buffer cache.
How UUID v7 Solves This: Because UUID v7 places a 48-bit millisecond timestamp at the head of the identifier, newly generated keys are strictly increasing over time. The database engine appends rows sequentially to the rightmost leaf page of the B-tree. Page splits are practically eliminated, disk pages fill to 95%+ density, and write performance matches auto-incrementing integers while preserving decentralized generation.
When to Choose UUID v4 vs. UUID v7
| Scenario / Architectural Requirement | Recommended Version | Technical Rationale |
|---|---|---|
| Database Clustered Primary Keys | UUID v7 | Maintains B-tree locality, eliminates page splits, and speeds up range queries on creation dates. |
| Public API Tokens & Reset Tokens | UUID v4 | Provides 122 bits of pure unpredictability. UUID v7 leaks creation timestamps, which attackers can exploit. |
| Client-Side Browser Generation | UUID v4 | Natively supported across all modern browsers via Web Crypto API (crypto.randomUUID()) without third-party JS bundles. |
| Audit Logs & Event Sourcing | UUID v7 | Events sort chronologically out-of-the-box without requiring a secondary created_at index. |
| Cache Keys & Idempotency Keys | UUID v4 | Completely opaque, uniform distribution across distributed Redis or Memcached clusters. |
UUIDs vs. Auto-Incrementing IDs (SERIAL / BIGINT)
Many developers ask whether they should abandon standard auto-incrementing integers entirely in favor of UUIDs. The table below highlights the concrete architectural trade-offs between a 64-bit BIGINT and a 128-bit UUID:
| Comparison Metric | Auto-Incrementing Integer (BIGINT) | UUID (v4 or v7) |
|---|---|---|
| Storage Footprint | 8 Bytes per row | 16 Bytes in binary (or 36 bytes if improperly stored as string) |
| Decentralized Generation | No (Central DB bottleneck) | Yes (Generated anywhere: clients, microservices, offline) |
| Enumeration Attack Risk | High (Users can scrape /orders/101, 102...) | None (Values cannot be guessed or sequentialized) |
| Business Metric Leakage | High (Competitors track order volume by ID growth) | Protected (Keys reveal no transaction volumes) |
| Distributed Sharding & Merging | Extremely complex (Key collision during DB merges) | Trivial (Records merge across tables with zero collision risk) |
A proven design pattern in enterprise systems is to use an internal BIGINT primary key for foreign-key join performance, alongside an indexed public-facing UUID column exposed in external APIs and URLs.

Collision Mathematics: What Are the Real Odds of a Duplicate UUID?
A frequent concern among software architects is whether UUID v4 identifiers can collide. Because UUID v4 relies on randomness rather than coordination, collisions are theoretically possible. However, the mathematics of probability demonstrates that in practice, a collision is so infinitesimally unlikely that it can be treated as zero.
The Birthday Problem for 122 Bits of Entropy
Evaluating collision risk is an application of the famous Birthday Paradox. In a room of 23 people, there is a 50% probability that at least two share the exact same birthday, despite there being 365 days in a year. This happens because collisions depend on the number of possible pairs of people (which grows quadratically as n(n - 1) / 2), not on the number of days.
For a random identifier with $N$ possible outcomes and $n$ generated items, the probability $P$ of at least one duplicate occurring is approximated by the mathematical formula:
For UUID version 4, the number of random bits is 122. Therefore:
When the collision probability is very small, we can apply the Taylor series expansion ($1 - e^{-x} \approx x$), simplifying the equation to:
Worked Probability Calculations across Scale
Let us compute the actual collision probabilities for various generation scales using verified mathematics:
-
Generating 1 Million UUIDs (n = 106):
P ≈ (106)² / (1.063 × 1037) = 1012 / 1.063 × 1037 ≈ 9.4 × 10⁻²⁶
The probability is effectively zero. You are billions of times more likely to be hit by a falling meteorite while holding a winning Powerball ticket.
-
Generating 1 Billion UUIDs (n = 109):
P ≈ (109)² / (1.063 × 1037) = 1018 / 1.063 × 1037 ≈ 9.4 × 10⁻²⁰
If you generate 1 billion records, the odds of a duplicate are less than 1 in 10 quintillion.
-
Generating 100 Trillion UUIDs (n = 1014):
P ≈ (1014)² / (1.063 × 1037) = 1028 / 1.063 × 1037 ≈ 9.4 × 10⁻¹⁰
Even after generating 100 trillion unique keys across global data centers, the chance of a single collision is still less than 1 in 1 billion.
-
The 50% Birthday Collision Bound:
To achieve a coin-flip 50% chance of a single collision, an application would need to generate:
n ≈ √(2 × 2122 × ln 2) ≈ 2.71 × 10¹⁸ UUIDs (2.71 quintillion identifiers)
If a hyper-scale cluster generated 1 billion UUIDs every second without stopping, it would take over 85 continuous years to reach a 50% probability of generating one duplicate.
How to Generate UUIDs Across Modern Programming Languages
Generating cryptographically secure UUID version 4 strings in modern software requires no external dependencies in most programming environments:
JavaScript and Node.js
Modern web browsers and Node.js (v14.17+) include native support via the Web Cryptography API. It runs natively in C++ inside the V8 engine without external libraries:
// Native Web Crypto API (Browser & Node.js)
const id = crypto.randomUUID();
console.log(id); // "f47ac10b-58cc-4372-a567-0e02b2c3d479"
Python
Python provides the built-in uuid module in its standard library:
import uuid

# Generate a cryptographically secure random UUID v4
unique_id = uuid.uuid4()
print(str(unique_id))  # "c9a646d3-9c61-4cd9-bc15-4dda295b4d11"
Go
Go developers standardly use the official Google UUID package:
package main

import (
    "fmt"
    "github.com/google/uuid"
)

func main() {
    id := uuid.New()
    fmt.Println(id.String())
}
PostgreSQL
PostgreSQL includes native 128-bit UUID support. Since PostgreSQL 13, the gen_random_uuid() function is built into core without requiring the pgcrypto extension:
CREATE TABLE accounts (
    id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    email VARCHAR(255) NOT NULL,
    created_at TIMESTAMPTZ DEFAULT NOW()
);
Step-by-Step Guide: Generating UUIDs with CoditTools
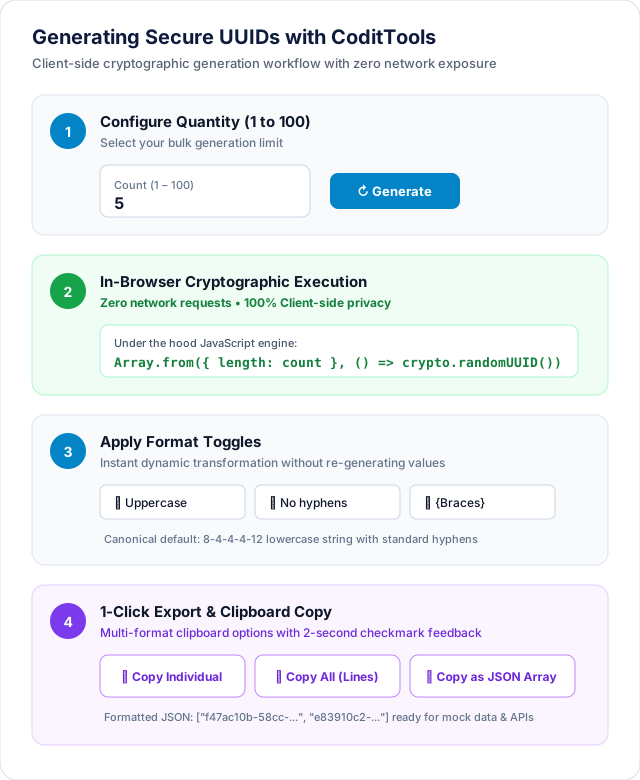
When you need mock data for test suites, temporary session tokens, or batch identifiers for database seeding, you do not need to boot up a programming environment or install command-line CLI tools. The CoditTools UUID Generator provides an instant, private utility directly in your web browser:
-
Configure Batch Quantity (1 to 100):
Specify the number of identifiers you require in the Count field. The tool enforces a minimum of 1 and a maximum limit of 100 identifiers per generation batch, defaulting to 5 on initial load.
-
In-Browser Cryptographic Execution:
Click the blue Generate button. The tool executes
crypto.randomUUID()locally on your device's processor using your browser's built-in cryptographic engine. No data is transmitted across the internet, ensuring 100% security and total privacy for sensitive workflows. -
Apply Real-Time Format Toggles:
Customize the output layout without re-running the generation engine:
- Uppercase: Formats hex letters to capital characters (useful for legacy enterprise schemas and Windows APIs).
- No hyphens: Strips the 4 hyphens to yield compact 32-character hex strings.
- {Braces}: Encloses each identifier in curly braces for Windows Registry, COM GUID, and C# schemas.
-
1-Click Clipboard Export:
Copy an individual identifier with its dedicated copy icon, click Copy All to grab a clean newline-separated list, or click Copy as JSON array to export structured test fixtures ready to paste directly into your automated test suites.
Generate Cryptographically Secure UUIDs Now
Create up to 100 random UUID v4 identifiers in your browser with zero latency, complete offline privacy, and instant JSON export.
5 Common UUID Mistakes Developers Make
Even seasoned software engineers make subtle architectural errors when implementing UUIDs in production systems:
-
Storing UUIDs as VARCHAR(36) in SQL Databases:
A canonical UUID string is 36 ASCII characters, requiring 36 bytes of storage. But the underlying identifier is only 16 bytes! Storing UUIDs as
VARCHAR(36)wastes 20 bytes per row, inflates B-tree index sizes by 125%, and severely degrades cache efficiency. Always use the nativeUUIDcolumn type in PostgreSQL orBINARY(16)in MySQL. -
Treating UUIDs as Secret Bearer Tokens:
While UUID v4 has 122 bits of randomness, it is a unique identifier, not a secure access token or password. UUIDs frequently appear in browser URLs, server access logs, and referrer headers. Never rely solely on possession of a UUID to grant administrative privileges without proper authentication and cryptographic signatures (such as HMAC or JWTs).
-
Using Math.random() to Construct UUIDs:
Legacy JavaScript snippets often used
Math.random()inside a regex replace block. Standard pseudo-random number generators (PRNGs) are not cryptographically secure and have short period lengths, resulting in catastrophic collision clusters under concurrent traffic. Always use the Web Cryptography API (crypto.randomUUID()orcrypto.getRandomValues()). -
Exposing UUID v1 in Public-Facing APIs:
Using UUID v1 in user profile URLs or public API endpoints reveals the server's physical network MAC address and exact creation timestamp to malicious actors, enabling network fingerprinting and targeted exploits.
-
Clustering Heavily Written Tables on Random UUID v4:
Placing a clustered primary key on UUID v4 in high-write transactional tables inevitably causes random I/O bottlenecks and index fragmentation. If you use PostgreSQL or MySQL for high-volume writes, adopt sequential UUID v7 or maintain a separate sequential clustered index.
Frequently Asked Questions
Is a UUID completely guaranteed to never collide?
Technically, UUID version 4 is probabilistic rather than mathematically absolute. However, because there are 2122 combinations (5.3 undecillion), the probability of generating a duplicate is lower than the probability of an uncorrectable cosmic-ray hardware memory error flipping a bit in your CPU. For all practical engineering purposes, UUID v4 collisions are impossible.
Can I reverse-engineer or decrypt a UUID?
UUIDs are identifiers, not encrypted messages. There is no plaintext or secret key inside a UUID. For UUID v4, the bits are pure random noise with zero embedded metadata. For UUID v1 and v7, the timestamp bits can be extracted to reveal when the identifier was created, but there is no underlying secret data to decrypt.
Why are hyphens used in UUID formatting?
The four hyphens in the 8-4-4-4-12 pattern were established in the original 1980s Apollo Network Computing System (NCS) and DCE standards to delineate internal bit fields (time_low, time_mid, time_hi, clock_seq, and node). While the hyphens add 4 bytes to the string representation, modern parsers ignore them, and our online generator allows you to strip them instantly.
What is the difference between RFC 4122 and RFC 9562?
RFC 4122 was published in July 2005 and established UUID versions 1 through 5. In May 2024, the IETF published RFC 9562, which formally obsoleted RFC 4122. RFC 9562 introduced three new versions: UUID v6 (reordered v1 timestamp), UUID v7 (Unix Epoch millisecond timestamp + random bits for database B-trees), and UUID v8 (custom experimental layouts).
Can UUID v7 replace ULID?
Yes. Universally Unique Lexicographically Sortable Identifiers (ULIDs) were created by the open-source community to solve the exact B-tree fragmentation issue that UUID v4 suffered from. RFC 9562 standardized UUID v7 to solve this natively within the formal IETF UUID namespace. Because UUID v7 uses standard 128-bit UUID binary layouts, it integrates natively into database UUID column types without custom Crockford Base32 codecs.
Conclusion & Best Practices
UUIDs are among the most essential building blocks of modern decentralized systems. By eliminating centralized coordination bottlenecks, they enable distributed microservices, cloud applications, and offline mobile clients to mint globally unique identifiers with total confidence.
For general application tokens, public references, mocking, and API keys, UUID version 4 remains the gold standard of unpredictability and security. When designing high-throughput relational database tables with clustered B-tree indexes, adopt UUID version 7 to eliminate page splits while preserving decentralized generation.
Whenever you need to generate cryptographically random identifiers, format GUIDs with custom casings or braces, or export mock fixtures for testing, open the CoditTools UUID Generator and explore our full range of browser-based utilities in the Developer Tools suite.
Try the tools mentioned in this post - all free, no account needed.
Runs in your browser. No watermarks. No file uploads to a server.
Browse developer tools →